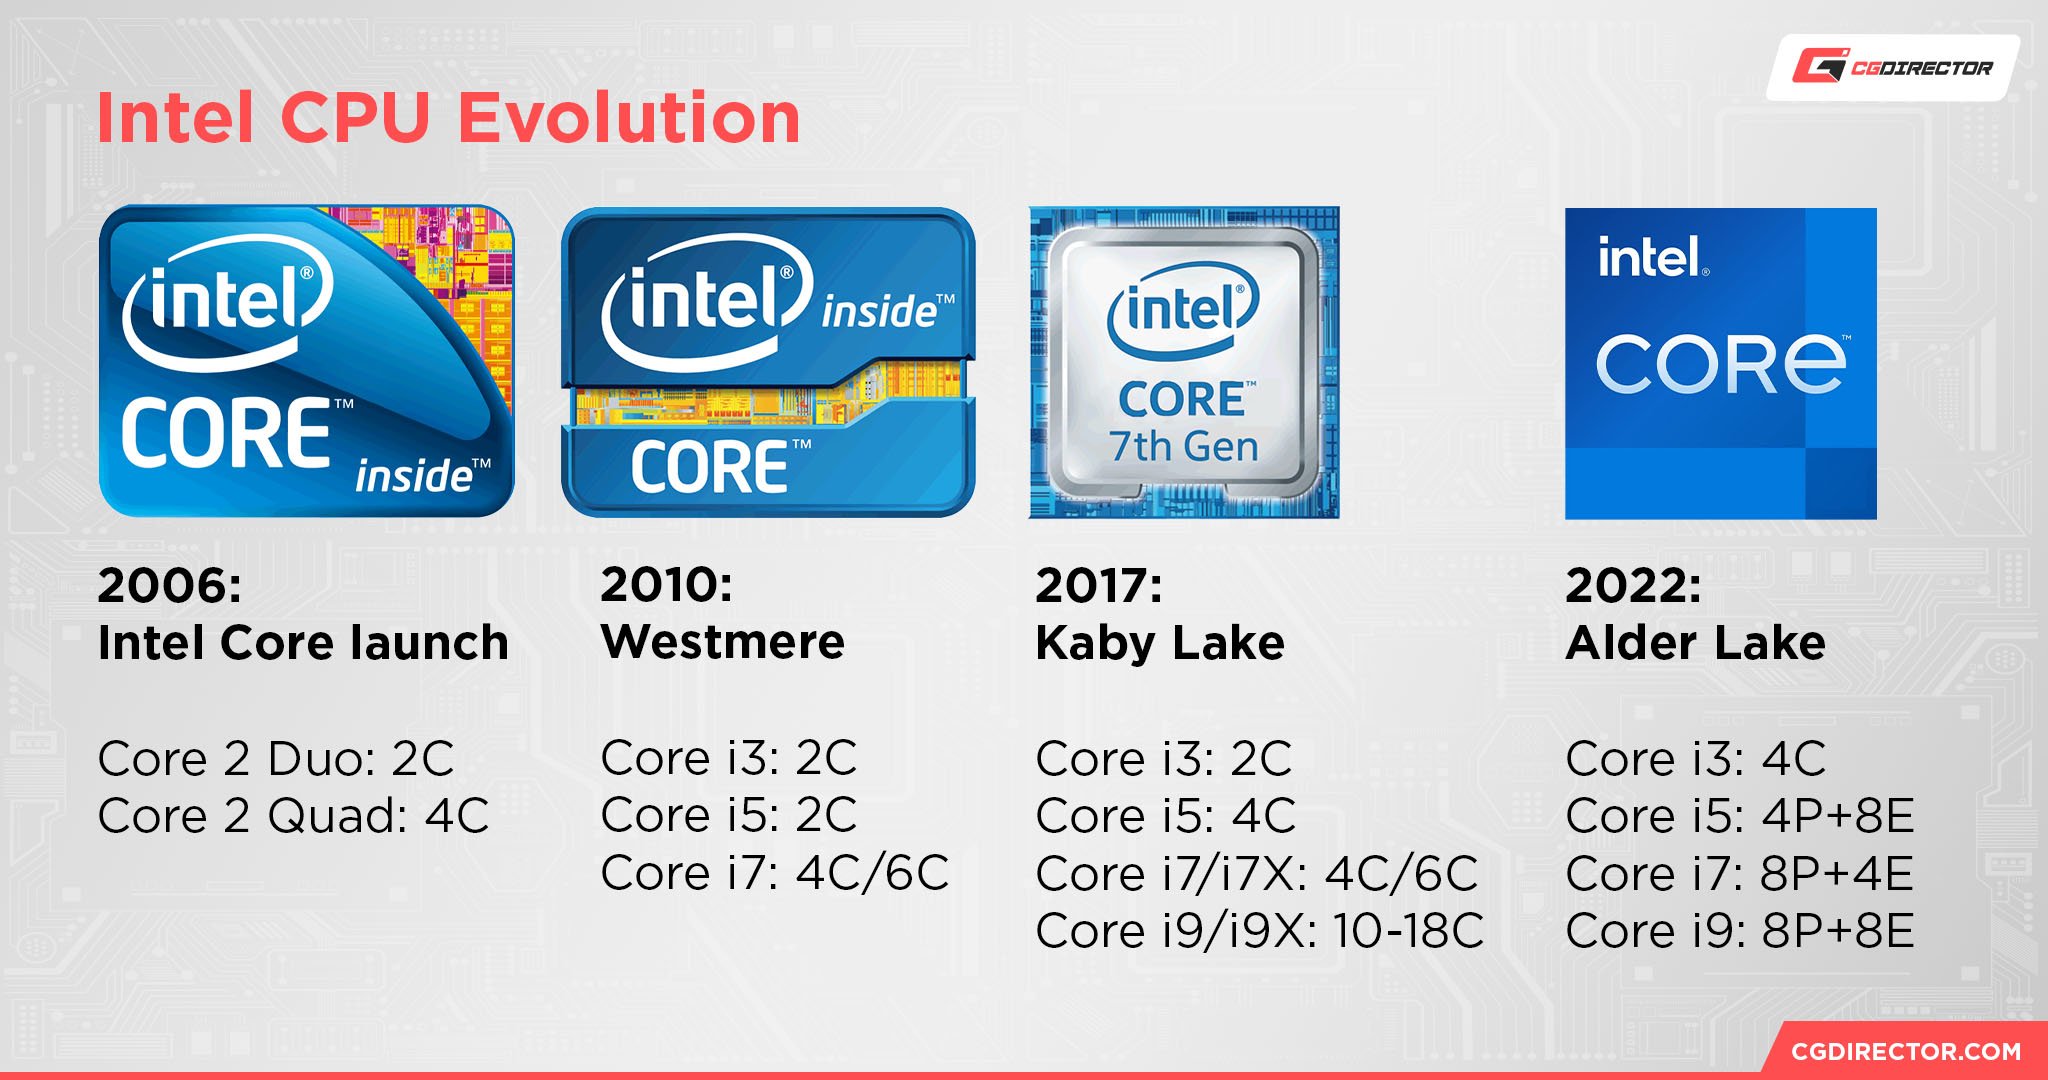
Modern hardware engineering centers on architectural efficiency and specialized processing blocks rather than raw clock speed scaling. Recent silicon rollouts emphasize heterogeneous core layouts, native neural processing units, and advanced packaging techniques that alter how personal computers and data centers handle intensive workloads.
This overview breaks down current Intel microarchitecture updates, how client and server lineups manage power and thermal constraints, and what these silicon revisions mean for developers, system builders, and enterprise deployments.
The Shift to Heterogeneous Core Architectures
Traditional processor designs relied on homogeneous cores running at identical clock frequencies. Modern workloads, however, range from background OS telemetry to multi-threaded video rendering. To handle this disparity efficiently, modern Intel core designs utilize a hybrid layout split between Performance-cores (P-cores) and Efficient-cores (E-cores).
P-cores focus on single-thread execution speed, instruction-per-clock throughput, and high-frequency operation for latency-sensitive tasks like gaming or compilation. E-cores target multi-threaded density, packing multiple execution units into a smaller silicon footprint while consuming a fraction of the power required by a P-core.
An intelligent hardware scheduler—built directly into the operating system kernel via Intel Thread Director—monitors thread execution in real time. It assigns tasks to the appropriate core type based on thermal budgets, battery states, and immediate computational demands. This approach maximizes multi-core benchmark scores without driving thermal design power (TDP) past sustainable limits in thin client form factors.
Integrated Neural Processing Units (NPUs)
As software stacks incorporate machine learning for local tasks—such as real-time audio filtering, background blur, predictive text generation, and local language models—running these algorithms solely on the CPU or discrete GPU introduces heavy energy penalties.
Recent processor generations integrate dedicated AI acceleration hardware known as Neural Processing Units (NPUs). These low-power inference engines offload repetitive matrix math operations from the main execution cores.
- Power Efficiency: NPUs execute low-precision inference tasks (such as INT8 operations) with minimal electrical draw compared to general-purpose execution units.
- Thermal Headroom: By isolating AI workloads onto a dedicated silicon block, the CPU and GPU retain thermal headroom for bursty application performance.
- Local Privacy: Running local models on dedicated hardware lets users process voice recognition and vision tasks on-device without streaming telemetry to cloud servers.
Advanced Packaging and Process Nodes
Manufacturing modern silicon requires moving away from monolithic dies toward modular, tile-based approaches. By separating the compute engine, I/O controller, and graphics block into distinct tiles interconnected through advanced packaging technologies like Intel Foundry Services, manufacturers bypass the yield walls associated with large single-die wafers.
This disaggregated approach allows different components of the processor to be fabricated on the most suitable manufacturing node. High-frequency compute blocks can use cutting-edge lithography nodes, while input/output interfaces can remain on more mature, cost-effective nodes. This reduces production waste and speeds up iteration cycles for individual silicon blocks.
Client vs. Enterprise Deployments
Silicon requirements diverge sharply between consumer endpoints and server infrastructure. Understanding these distinct pathways clarifies where engineering investments land.
Consumer Workstations and Laptops
Client platforms prioritize burst responsiveness, battery longevity, and acoustic management. Dynamic voltage and frequency scaling (DVFS) algorithms react to microsecond load shifts, dropping core voltages instantly when idle. Integrated graphics architectures have also evolved, supporting advanced hardware video decode pipelines (such as AV1 encoding) to reduce CPU overhead during media playback and streaming workflows.
Enterprise Data Centers
Data center deployments prioritize throughput density, memory channel bandwidth, and RAS (Reliability, Availability, and Serviceability) features. Server-grade silicon architectures emphasize massive core counts, specialized instruction sets for database encryption and vector math, and extensive PCIe lane allocations to support dense NVMe storage arrays and multi-GPU accelerator clusters.
Common System Integration Pitfalls
When upgrading hardware or building new systems around recent processor updates, administrators and enthusiasts often run into predictable bottlenecks:
- Inadequate Memory Topology: Running high-core-count processors with mismatched or single-channel memory configurations starves the memory controller, limiting overall throughput.
- Thermal Throttling Oversight: Ignoring motherboard power delivery limits (PL1/PL2 thresholds) can cause processors to downclock prematurely during sustained rendering or compilation workloads.
- Outdated OS Kernels: Older operating system versions lack support for hardware schedulers, leading to threads being assigned to inefficient core types during heavy multitasking.
Frequently Asked Questions
Do older motherboards support new processor generations?
Socket compatibility changes across microarchitecture generations due to altered pin layouts and updated power delivery requirements. Always verify the specific motherboard chipset and BIOS version before attempting cross-generation upgrades.
How does Thread Director affect Linux versus Windows environments?
While Windows has native kernel support for hybrid core scheduling, modern Linux distributions incorporate comparable scheduling enhancements (such as split-capacity scheduling patches) to map tasks correctly between P-cores and E-cores.
Are NPUs required for standard gaming performance?
No. NPUs are specialized for low-latency inference tasks like machine vision and audio processing. Traditional gaming performance relies primarily on P-core clock speeds, cache capacity, and discrete GPU throughput.
What is the practical advantage of disaggregated packaging?
Disaggregated packaging lowers manufacturing costs and improves production yields by building smaller, modular tiles rather than a single massive monolithic die, allowing faster iteration across different functional blocks.



